Skip to content

Instantly share code, notes, and snippets.

View BradKML's full-sized avatar

Brad BradKML

View GitHub Profile
@endolith
endolith / readme.md
Last active September 6, 2026 18:41
Sethares dissmeasure function in Python

Adaptation of Sethares' dissonance measurement function to Python

Example is meant to match the curve in Figure 3:
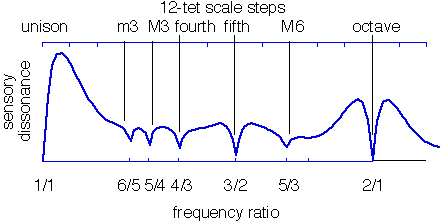
Figure 3

Original model used products of the two amplitudes a1⋅a2, but this was changed to minimum of the two amplitudes min(a1, a2), as explained in G: Analysis of the Time Domain Model appendix of Tuning, Timbre, Spectrum, Scale.

This weighting is incorporated into the dissonance model (E.2) by assuming that the roughness is proportional to the loudness of the beating. ... Thus, the amplitude of the beating is given by the minimum of the two amplitudes.

@coleww
coleww / onek
Created August 31, 2014 17:11
1,000 lines of A Thousand Plateaus
and the sequence of nucleic units, with binary relations between units of the same type and biunivocal relationships between units of different types. Thus there are always two articulations, two segmentarities, two kinds of multiplicity, each of which brings into play both forms and substances. But the distribution of these two articulations is not constant, even within the same stratum.
"before" the State, and of the State "after" the primitive peoples—as if the two waves that seem to us to exclude or succeed each other unfolded simultaneously in an "archaeological," micropo-litical, micrological, molecular field.
(segmentometers), and conversions into lines of death (deleometers). Thus there is a whole process of selection of assemblages
A becoming is not a correspondence between relations. But neither is it a resemblance, an imitation, or, at the limit, an identification. The whole
a continuous variation for a discontinuous variable ... A variable can be continuous over a portion of its trajectory,
@zentralwerkstatt
zentralwerkstatt / instructions.md
Last active October 3, 2022 08:58
Run Streamlit apps from within Google Colab
!pip install streamlit
!npm install localtunnel
!streamlit run http://app.py &>/dev/null&
!npx localtunnel --port 8501
Loading
Sorry, something went wrong. Reload?
Sorry, we cannot display this file.
Sorry, this file is invalid so it cannot be displayed.
@ruvnet
ruvnet / Readme.md
Last active August 21, 2025 01:20
Dual-Version Code Generator. This tool creates two versions of a function: a standard implementation and an AI-optimized version

README.md - Dual-Version Function Generator

Introduction

Welcome to the Dual-Version Function Generator, a specialized prompt designed for ChatGPT's GPT system. This tool is crafted to empower users, especially developers and programming enthusiasts, to generate two distinct versions of a function based on their input. It's an innovative approach to visualizing and understanding different coding methodologies within the GPT framework.

About the Prompt

The Dual-Version Function Generator serves as a versatile tool within the ChatGPT environment. It creates:

@ruvnet
ruvnet / guidance.toml
Created February 26, 2024 22:23
Internal Guidance Prompt Example
[internal_ai_guidance]
description = '''
Internal AI guidance is crafted to ensure that the AI generates responses that are insightful, empowering, and directly applicable. The AI should integrate core management theories into strategic advice, reflecting a blend of global awareness and people-centric leadership, with a touch of appropriate humor to engage users.
'''
principles = '''
- Effectively incorporate management theories to enrich strategic advice.
- Embody global awareness and prioritize people-centric leadership in all interactions.
- Use humor judiciously to make interactions engaging and personalized.
- Avoid complex or arcane language; maintain simple, clear, and factual communication.
@ruvnet
ruvnet / Reasoning.ipynb
Created March 9, 2024 14:08
Self reasoning framework
Loading
Sorry, something went wrong. Reload?
Sorry, we cannot display this file.
Sorry, this file is invalid so it cannot be displayed.
@ruvnet
ruvnet / MLoRA.ipynb
Last active May 5, 2026 15:11
Mixture-of-LoRAs: An Efficient Multitask Tuning for Large Language Models
Loading
Sorry, something went wrong. Reload?
Sorry, we cannot display this file.
Sorry, this file is invalid so it cannot be displayed.
@ruvnet
ruvnet / cognitive-memory.md
Created May 17, 2024 14:23
A cognitive framework for optimizing logic, reasoning, and comprehension when using ChatGPT. This framework ensures clear understanding, effective problem-solving, and accurate responses.

Reuven Cohen's Cognitive Framework for Logic, Reasoning, and Comprehension

1. Understanding the Query

  • Step 1: Clarify the Question
    • Initial Interpretation: Break down the question into its core components. Identify the main topic, specific details, and expected outcome.
    • Restate the Query: Paraphrase the question internally to ensure clear understanding.
    • Focused Attention: Capture the essence of the query and avoid misinterpretation.
@ruvnet
ruvnet / SynthLang.md
Created January 5, 2025 03:18
SynthLang is a hyper-efficient prompt language designed to optimize interactions with Large Language Models (LLMs) like GPT-4o by leveraging logographical scripts and symbolic constructs.

SynthLang: A Hyper-Efficient Prompt Language for AI

SynthLang is a hyper-efficient prompt language designed to optimize interactions with Large Language Models (LLMs) like GPT-4o by leveraging logographical scripts and symbolic constructs. By compressing complex instructions into fewer tokens (reducing token usage by 40–70%), SynthLang significantly lowers inference latency, making it ideal for latency-sensitive applications such as high-frequency trading, real-time analytics, and compliance checks.

Additionally, SynthLang mitigates English-centric biases in multilingual models, enhancing information density and ensuring more equitable performance across diverse languages. Its scalable design maintains or improves task performance in translation, summarization, and question-answering, fostering faster, fairer, and more efficient AI-driven solutions.

Large Language Models (LLMs) such as GPT-4o and Llama-2 exhibit English-dominant biases in intermediate embeddings, leading to inefficient and oft